Web development
Technical SEO: a verifiable audit protocol for a website’s foundations
A useful technical SEO audit does not collect alerts. It connects every possible failure to a replayable test, evidence, severity, an owner and an explicit decision.
- 13 domains From HTTP transport to AI agents.
- 44 checks Published method and expected evidence.
- 4 statuses Untested never means compliant.
- 0 promises No ranking, traffic or rich-result guarantee.
Short answer
Technical SEO reduces uncertainty between a published URL and a page that search systems can actually discover, crawl, render, index, understand and serve.
Technical SEO is not a collection of green checks in a crawler. It makes every decision replayable: which URL must respond, who may crawl it, which version should be canonical, when the content becomes available, what evidence establishes the result and which failure must stop a release.
A useful audit separates four layers that are too often merged: publicly observable evidence, Search Console evidence, server-log evidence and remaining hypotheses. It promises neither rankings nor traffic. It removes technical breaks that prevent systems from processing the intended page.
Four markers for reading the protocol without confusing a check with a promise.
technical domains covered.
documented, replayable checks.
controlled statuses for decisions.
ranking guarantees.
An untested check is not compliant. A public observation is not Search Console evidence. One critical failure can impose NO-GO, regardless of the number of green checks.
Evidence boundary
Four evidence levels prevent a public audit from pretending to know private states.
| Level | Examples | Establishes | Does not establish |
|---|---|---|---|
| Public | HTTP, robots.txt, source HTML, rendered DOM, sitemap, JSON-LD. | The response obtained from a documented context and time. | What Google crawled, selected or indexed. |
| Search Console | URL Inspection, Google-selected canonical, Pages and Core Web Vitals reports. | The state reported for the observed property and sample. | The single cause of a ranking change. |
| Server logs | Verified bot requests, status codes, frequency, URLs and bytes served. | An interaction received by the infrastructure, subject to bot verification. | How the system subsequently used the content. |
| Configuration | WAF, CDN, application, CMS and deployment rules. | The configured intent and rule, when tested. | That every layer applies the same policy. |
This method is published by Edikka, a web development, SEO and AI-visibility agency. It is neither an independent standard nor a certification. Thresholds rely on primary specifications and documentation; final decisions depend on the site’s context, risk and private evidence.
Causal model
Discovery, crawling, rendering, indexing and serving are different stages.
Calling a page “SEO-friendly” hides the stage that failed. A URL may be discovered but blocked, crawled but rendered without critical content, indexed under another canonical, or indexed without being selected for a query. Diagnosis starts by locating that break.
| Stage | Question | Useful evidence | Common mistake |
|---|---|---|---|
| Discovery | Does a public path lead to the URL? | HTML link, sitemap, referring URL in logs. | Equating sitemap presence with internal discoverability. |
| Crawling | May the crawler request the resource? | robots.txt, HTTP response, verified logs. | Using Disallow as a deindexing mechanism. |
| Rendering | Does critical content exist after execution? | Source HTML, rendered DOM, URL Inspection. | Treating JavaScript as inherently bad. |
| Indexing | Which URL and content does the engine retain? | URL Inspection, Google canonical, Pages report. | Inferring indexation from a 200 response. |
| Serving | Is the page selected for a query and context? | Search performance and observed results. | Attributing a position to one technical factor. |
Open grid v1.1
The protocol covers 13 domains and 44 checks.
The number of checks varies with risk: a symmetrical table must not dictate the audit. The public JSON dataset v1.1 is the canonical source for identifiers, methods, evidence, sources and limitations. The indexable HTML table and XLSX workbook are generated from it.
Identifiers TS01 through TS44 remain stable between versions. Cite a precise check with its fragment, for example #TS41.
| IDs | Domain | Primary decision | Evidence often missing |
|---|---|---|---|
| TS01–03 · TS37 | HTTP and availability | Which response and transport should be served? | Final GET, chain, certificate and HSTS. |
| TS04–06 | Robots and access | Crawl, index or protect? | Server-layer test. |
| TS07–09 | Indexation | Which pages must remain indexable? | Search Console inspection. |
| TS10–12 | Canonicalisation | Which URL represents the content? | Google-selected canonical. |
| TS13–15 | Sitemaps and freshness | Which URLs should be declared, and when? | lastmod tied to a real modification. |
| TS16–18 | Internal discoverability | How is each useful page reached? | Crawler, CMS and sitemap comparison. |
| TS19–21 · TS38 | URL spaces | Which parameters and variants are normalised? | Segmentation, host, case and trailing slash. |
| TS22–24 · TS40 | Internationalisation | Which locale and hreflang source? | Reciprocity in HTML, HTTP or sitemap. |
| TS25–27 | JavaScript and rendering | At which stage does content exist? | Source, render and inspection compared. |
| TS28–30 | HTML and semantics | Does the document remain understandable? | Structure and crawlable links. |
| TS31–33 | Structured data | Which entities are actually visible? | A graph without invented entities. |
| TS34–36 · TS39 · TS41 | Performance and monitoring | Which experience, edge and non-regression controls? | CrUX, CDN, CI, logs and deployments. |
| TS42–44 | AI crawlers and agents | Which access for search, action and training? | Purpose-specific policy, full GET and logs. |
Canonical public inventory
All 44 checks are available in indexable HTML.
This table is generated from the same JSON source as the workbook. Each row publishes the method, expected evidence, required access, default severity, primary source and explicit limitation. A consumer can therefore cite or replay one check without inferring the rest of the protocol.
| ID | Domain | Check | Method | Expected evidence | Access | Severity | Source and limit |
|---|---|---|---|---|---|---|---|
| TS01 | HTTP and availability | The final page returns an actionable HTTP status code. | Send a GET request, follow redirects and record the final status code. | Tested URL, timestamp and final 200 status for a public canonical page. | Public | Blocking | Primary sourceA test from one IP does not prove the response received by Googlebot. |
| TS02 | HTTP and availability | Redirects are intentional, direct and loop-free. | Test HTTP/HTTPS, host, trailing-slash and legacy URL variants, including the redirect count. | One final destination, documented chain and no loop. | Public | Major | Primary sourceA valid redirect does not prove the semantic relevance of its destination. |
| TS03 | HTTP and availability | Server errors and soft 404s do not replace an explicit response. | Test an existing page, a removed URL and a non-existent URL; compare status and content. | Consistent 4xx/5xx responses and an error template that does not return 200 by default. | Public | Major | Primary sourceThe final soft-404 classification remains a search-engine decision. |
| TS04 | Robots and access | robots.txt is accessible, parseable and does not block required resources. | Fetch /robots.txt and inspect its content type, groups and applicable rules. | A 200 response, readable syntax and rules tied to a documented intent. | Public | Blocking | Primary sourcerobots.txt is a crawling protocol, not an access-control mechanism. |
| TS05 | Robots and access | A Disallow rule is never presented as a guarantee of deindexing. | Compare the robots policy, indexing requirements and meta/X-Robots-Tag directives. | Separate decisions for crawling, indexing and protection. | Configuration | Blocking | Primary sourceA blocked URL may remain known and appear without a snippet. |
| TS06 | Robots and access | Sensitive areas genuinely deny access at server level. | Test private routes without a session and verify authentication, authorisation and caching. | A 401/403 response or authentication redirect, with no sensitive content delivered. | Configuration | Blocking | Primary sourceAbsence from the index is not proof of confidentiality. |
| TS07 | Indexing | Robots meta directives and X-Robots-Tag match the page objective. | Inspect headers and source DOM across indexable and excluded templates. | One directive or a compatible combination, with no accidental noindex. | Public | Blocking | Primary sourceThe engine must be allowed to crawl the resource to read the directive. |
| TS08 | Indexing | The actual indexing status is checked in Search Console. | Use URL Inspection on a representative sample and retain the export or screenshot. | Known URL, crawling permission, indexing state and Google-selected canonical documented. | Search Console | Major | Primary sourceA public audit cannot establish this status without property access. |
| TS09 | Indexing | Intentional exclusions have an owner and a rationale. | Tie each excluded family to a rule, owner and review date. | Exclusion register: page type, mechanism, rationale, owner and review. | Configuration | Minor | Primary sourceThe business relevance of an exclusion cannot be automated. |
| TS10 | Canonicalisation | Each canonical page publishes an absolute, stable and consistent URL. | Compare the final URL, rel=canonical, sitemap and internal links. | Signals converge on the same canonical URL without a chain. | Public | Major | Primary sourcerel=canonical is a strong signal, not a guaranteed directive. |
| TS11 | Canonicalisation | Genuine duplicate variants converge without hiding distinct pages. | Sample parameters, pagination, filters and print versions; compare content and canonicals. | Documented mapping between each duplicate and its relevant canonical. | Public | Major | Primary sourceComputed similarity does not replace an editorial decision. |
| TS12 | Canonicalisation | Google’s selected canonical is compared with the declared canonical. | Inspect priority URLs and record the user-declared and Google-selected canonicals. | Agreement or a qualified, addressed divergence. | Search Console | Major | Primary sourceGoogle’s selected canonical can change after recrawling. |
| TS13 | Sitemaps and freshness | The sitemap contains only useful absolute canonical URLs. | Parse every sitemap, count URLs and compare status, canonical and indexability. | Inventory without redirects, 4xx responses, noindex pages or duplicate canonicals. | Public | Major | Primary sourceSitemap inclusion does not guarantee indexing. |
| TS14 | Sitemaps and freshness | lastmod reflects a significant change to the page. | Compare lastmod with editorial history or a significant content deployment. | ISO 8601 timestamp tied to an actual change, not file generation. | Configuration | Minor | Primary sourceThe engine may ignore a lastmod it considers unreliable. |
| TS15 | Sitemaps and freshness | Sitemap size and segmentation limits are respected. | Check uncompressed size, URL count, sitemap indexes and encoding. | No more than 50,000 URLs and 50 MB uncompressed per sitemap. | Public | Major | Primary sourceA valid file can still cover the wrong editorial scope. |
| TS16 | Internal discoverability | Every important page receives at least one crawlable internal link. | Crawl from public entry points and list pages with no incoming HTML link. | Link source, destination, anchor and destination status. | Public | Major | Primary sourceThe presence of a link does not prove its editorial value. |
| TS17 | Internal discoverability | Essential links use an a element with a resolvable href. | Compare source and rendered DOM; identify buttons, onclick handlers and anchors without href. | A crawlable HTML link to every essential destination. | Public | Major | Primary sourceCrawlability guarantees neither indexing nor rankings. |
| TS18 | Internal discoverability | Depth and orphan pages are measured within an explicit scope. | Compare crawl, sitemap and CMS export; qualify every difference. | Orphan list, observed minimum depth and a decision for each family. | Public | Major | Primary sourceNo universal depth guarantees rankings. |
| TS19 | URL spaces | Parameters, filters and calendars do not create an infinite URL space. | Group URLs by pattern, count combinations and look for crawl traps. | Indexing and navigation rule for each parameter pattern. | Public | Major | Primary sourceThe actual crawled volume requires logs or Search Console. |
| TS20 | URL spaces | The URL structure is readable, stable and correctly encoded. | Identify spaces, fragments, encoded characters, case and volatile identifiers. | Documented URL patterns and no unintended variants. | Public | Minor | Primary sourceA readable URL is not sufficient evidence of SEO performance. |
| TS21 | URL spaces | Discovered but unindexed URLs are investigated by family. | Segment the Pages report by template and compare it with sitemaps and logs. | Hypothesis per family, URL sample and post-fix result. | Search Console | Major | Primary sourceA Search Console label describes a state, not always its cause. |
| TS22 | Internationalisation | Each hreflang variant points to an indexable canonical URL. | Parse HTML, HTTP or sitemap annotations and resolve every URL. | Valid language/region, 200 response and consistent canonical. | Public | Major | Primary sourcehreflang helps targeting; it does not replace genuinely localised content. |
| TS23 | Internationalisation | hreflang annotations are reciprocal and include the current page. | Build variant clusters and verify return links and self-references. | Complete reciprocal cluster with no conflicting URL. | Public | Major | Primary sourceA valid cluster does not prove the engine will always serve the expected variant. |
| TS24 | Internationalisation | x-default represents a neutral destination or an explicit default variant. | Check its presence and role in every relevant multilingual cluster. | Documented, accessible x-default URL consistent with the journey. | Public | Minor | Primary sourcex-default is not mandatory in every case. |
| TS25 | JavaScript and rendering | Critical content exists in source HTML or becomes observable after rendering. | Compare the HTML response, rendered DOM and URL Inspection for critical elements. | Title, content, links, canonical and structured data present at the right stage. | Public | Blocking | Primary sourceA local browser does not reproduce Google’s rendering exactly. |
| TS26 | JavaScript and rendering | Resources required for rendering are neither blocked nor failing. | Inspect network activity, robots rules, CSP and console errors on priority templates. | Critical resources accessible and no error removes essential content. | Public | Major | Primary sourceAn error-free console does not prove indexing. |
| TS27 | JavaScript and rendering | SPA states and routes produce shareable URLs and consistent server responses. | Open routes directly and test refresh, history, canonical and HTTP status. | Each indexable view has its own URL, 200 response, content and signals. | Public | Major | Primary sourceChoosing SSR, CSR or SSG is not in itself an SEO guarantee. |
| TS28 | HTML and semantics | The document exposes an understandable HTML structure independently of appearance. | Inspect title, language, main landmark, heading levels, links and labels on a sample. | Logical structure, one identifiable main subject and accessible components. | Public | Major | Primary sourceSyntax validity alone proves neither quality nor relevance. |
| TS29 | HTML and semantics | Essential content remains available when scripts or styles fail. | Test source HTML, disabled JavaScript and degraded network conditions. | Primary information and navigation remain available, or a fallback is documented. | Public | Major | Primary sourceAcceptable degradation depends on the component’s function. |
| TS30 | HTML and semantics | Essential metadata is unique, visible and consistent with the page. | Compare title, description, H1, Open Graph and main content by template. | Consistent topic and promise without mechanical duplication. | Public | Major | Primary sourceGoogle may rewrite the title link or snippet in search results. |
| TS31 | Structured data | JSON-LD describes entities that are visible and appropriate to the content. | Compare each important property with visible content and type-specific guidance. | Valid, consistent graph with no invented entity or rating. | Public | Major | Primary sourceValid markup guarantees neither a rich result nor higher rankings. |
| TS32 | Structured data | Stable @id values connect the same entities without creating duplicates. | Build the graph and identify unnamed nodes, variable identifiers and duplicates. | Organization, Person, WebSite, WebPage and Article connected by stable @id values. | Public | Minor | Primary sourceSchema.org defines a vocabulary; interpretation depends on the consumer. |
| TS33 | Structured data | Errors, warnings and unsupported uses are distinguished. | Test Schema.org syntax and Google eligibility separately; record both results. | Report with no blocking error and qualified warnings. | Public | Minor | Primary sourceRich Results Test does not validate the whole Schema.org vocabulary. |
| TS34 | Performance and monitoring | Field Core Web Vitals are read at the 75th percentile. | Record LCP, INP and CLS from field data by device type and URL group. | LCP ≤ 2.5 s, INP ≤ 200 ms and CLS ≤ 0.1 at the 75th percentile for a Good assessment. | Search Console | Major | Primary sourceMissing CrUX data does not mean the page is fast. |
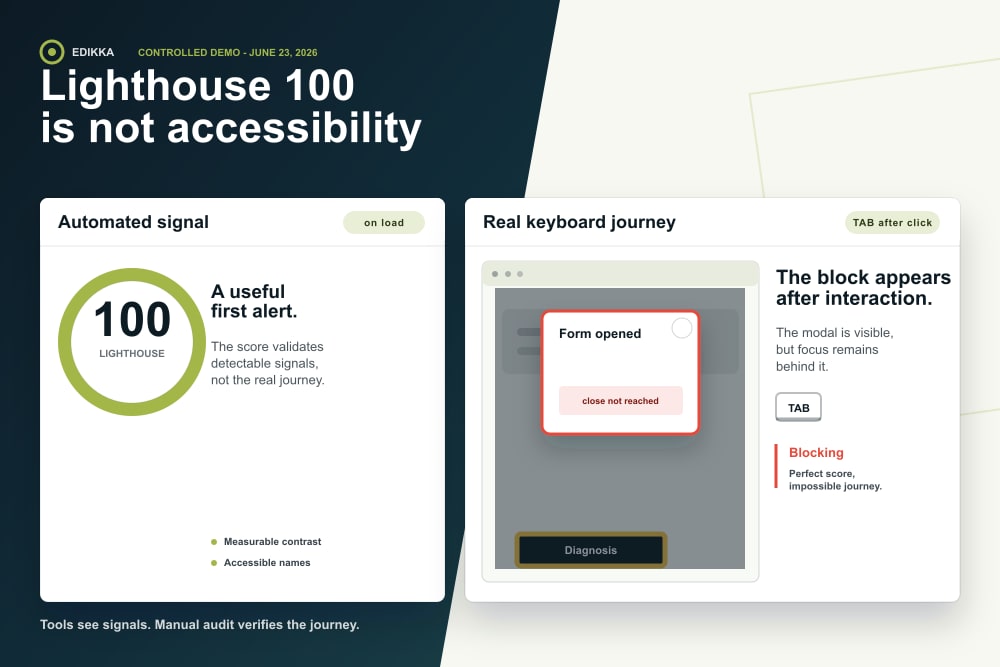
| TS35 | Performance and monitoring | Laboratory tests support diagnosis rather than simulate field data. | Retain URL, device, network profile, tool version and detailed metrics. | Reproducible Lighthouse/WebPageTest report tied to a remediation hypothesis. | Public | Minor | Primary sourceA Lighthouse score of 100 guarantees neither field CWV nor rankings. |
| TS36 | Performance and monitoring | Monitoring connects Search Console, logs and deployments to decision dates. | Create a pre-change baseline, then verify at D+1, D+7 and D+30 according to risk. | Deployment log, crawl/indexing anomalies and signed decisions. | Server logs | Major | Primary sourceTemporal correlation is not sufficient to attribute a traffic change. |
| TS37 | HTTP and availability | HTTPS, HSTS and embedded resources create neither certificate errors nor mixed content. | Test certificates on public hosts, follow HTTP/HTTPS variants, record Strict-Transport-Security and find HTTP subresources. | Valid certificate for each host, HTTPS redirect, documented HSTS header and no active HTTP resource. | Public | Major | Primary sourceHSTS strengthens transport after the policy is received; it fixes neither an invalid certificate nor a poor URL architecture. |
| TS38 | URL spaces | Host, case and trailing-slash variants converge on one rule. | Replay www/non-www, HTTP/HTTPS, relevant case and trailing-slash variants on sample routes; compare redirect, canonical, sitemap and links. | One stable final URL per resource, no chain and consistent internal signals. | Public | Major | Primary sourceCase can be significant depending on the server and application; the rule must be tested, not assumed. |
| TS39 | Performance and monitoring | The CDN, Vary and geolocation do not serve contradictory SEO signals. | Compare status, canonical, robots, language and content across regions or cache keys; inspect Vary, geolocation redirects and edge rules. | Identical SEO signals for the same URL, or explicitly documented variants accessible to Googlebot. | Configuration | Major | Primary sourceTwo test locations do not cover every route, POP or cache key. |
| TS40 | Internationalisation | The chosen hreflang method — HTML, HTTP header or sitemap — is complete and unique. | Identify the source of truth, then verify that every URL lists itself and all alternatives in that method. | Equivalent reciprocal clusters; when sitemaps are used, valid xhtml namespace and entries per URL. | Public | Major | Primary sourceCombining HTML, headers and sitemaps offers no search benefit and increases divergence risk. |
| TS41 | Performance and monitoring | Critical SEO invariants are replayed automatically before and after deployment. | Run a representative URL set in CI: final status, redirects, robots/noindex, canonical, hreflang, server content, essential links and JSON-LD. | Versioned command, timestamped output, explicit failure threshold and link to the relevant deployment. | Configuration | Major | Edikka method · no single primary sourceCI validates known invariants; it replaces neither Search Console, logs nor editorial review. |
| TS42 | AI crawling and agents | Each AI crawler is governed according to its actual purpose: search, user action or training. | Map search, user action and training separately — for example OAI-SearchBot / ChatGPT-User / GPTBot and Claude-SearchBot / Claude-User / ClaudeBot — to a dated decision and owner. | Table of user agent, purpose, rule, operator source and review date, without conflating live search with training. | Configuration | Major | Primary sourceA robots directive is declarative; it proves neither the requester’s identity nor compliance by every operator. |
| TS43 | AI crawling and agents | Access for authorised crawlers is tested with the full user-agent string and reconciled with logs. | Send a GET request using the documented full user-agent, record status and redirects, find the request in logs and verify identity when the operator publishes a method. | Command, full string, final response, timestamp, server trace and verified/unverified identity status. | Server logs | Major | Primary sourceImitating a user agent does not reproduce crawler infrastructure; the test validates application policy, not a real operator visit. |
| TS44 | AI crawling and agents | Critical content and evidence remain accessible without undocumented JavaScript execution. | Compare raw HTML, rendered content and any public machine-readable resource; verify titles, facts, sources, links and update date. | Essential facts and sources in server HTML or a linked public resource, with a consistent version and stable URL. | Public | Major | Primary sourceAn llms.txt or Markdown file may ease access, but neither guarantees citation nor rankings. |
Checks TS01–TS03
Test with GET, follow the complete redirect chain and include an error case.
A HEAD request alone is insufficient: a CDN, firewall or application can treat HEAD and GET differently. Record the final status, redirect count, effective URL and duration. Replay at least the canonical URL, an old URL, a removed resource and a nonexistent URL.
curl -L -sS -o /dev/null \
  -w 'HTTP %{http_code} · redirects %{num_redirects} · final %{url_effective} · %{time_total}s\n' \
https://www.example.com/page| Response | Interpretation | Action |
|---|---|---|
| 200 | The server delivers a representation; indexation is not proven. | Check content, directives and canonical. |
| 301 / 308 | The resource moved permanently. | Check destination, relevance and chain. |
| 302 / 307 | The HTTP move is temporary. | Verify that temporary behaviour is intentional. |
| 404 / 410 | The resource is unavailable. | Keep when removal is intended; avoid soft 404s. |
| 5xx | The server did not process the request. | Fix, log and monitor before release. |
Checks TS04–TS09
Disallow, noindex and server protection solve three different problems.
Disallow asks a compliant crawler not to crawl a path. It does not guarantee that the URL disappears from results. A noindex directive must be read in HTML or an HTTP header; if robots.txt blocks the resource, the crawler may never see it. Confidential data must be denied by server-side authentication and authorisation.
This corrects a common recommendation: combining noindex with Disallow does not automatically strengthen exclusion. It can prevent the noindex from being read. Google’s robots directives documentation and RFC 9309 define these boundaries.
| Intent | Primary mechanism | Evidence | Avoid |
|---|---|---|---|
| Reduce crawling | robots.txt, if the crawler complies. | Parsed rule plus logs. | Presenting the rule as security. |
| Remove from index | noindex accessible to the crawler. | URL Inspection after recrawl. | Blocking before noindex can be read. |
| Consolidate duplicates | Redirect or rel=canonical, depending on the case. | Converging signals plus Google canonical. | Canonicalising genuinely distinct pages. |
| Protect data | Server authentication and authorisation. | No-session test, 401/403, no content. | Publishing a secret and hiding it from robots. |
Checks TS10–TS12
A canonical is a strong signal; the search engine retains the final decision.
Google describes redirects and rel="canonical" as strong canonicalisation signals, and sitemap inclusion as weaker. Signals reinforce one another when they converge. They do not turn the declared canonical into an absolute order: the engine may select another URL.
The public check compares final URL, declared canonical, sitemap and internal links. The private check then compares user-declared and Google-selected canonicals in URL Inspection. Without that second step, the audit can conclude only that the declaration is coherent.
A canonical page should not redirect, be noindexed, contradict hreflang, or be excluded from its own internal-link strategy. A contradiction across these signals is a major defect, not a cosmetic warning.
Checks TS13–TS15
A sitemap is a declared inventory, not an indexation certificate.
Include only absolute, indexable candidate canonicals that return the intended status. A lastmod value must describe a meaningful page modification, not the time at which the sitemap was regenerated. Google ignores priority and changefreq; they must not become project KPIs.
Compare the sitemap against the crawler, CMS and analytics inventory. Gaps reveal orphan candidates, obsolete URLs, parameter spaces or pages accidentally excluded from navigation.
Checks TS16–TS18
Useful pages need crawlable HTML links and an intentional click path.
A visual click handler is not necessarily a crawlable link. Critical navigation should expose an <a href> destination in server-delivered or reliably rendered HTML. Compare the URL sets from internal crawl, sitemap and CMS to identify orphan pages and false depth.
Depth is not a universal ranking factor. It is an operational signal: if an important page requires many interactions, agents and users may struggle to discover it, and changes to upstream navigation carry disproportionate risk.
Checks TS19–TS21 and TS38
Parameters, faceting and URL variants must have an explicit indexation policy.
Inventory query parameters and classify them by function: content selection, filtering, sorting, tracking, pagination or session state. For every family, document whether it may be crawled, indexed, canonicalised, redirected or ignored. Apply the same discipline to host, protocol, case, duplicate slashes and trailing slash.
A rule that “removes parameters” without distinguishing their meaning can delete valid content states. A rule that keeps every combination can create an effectively unbounded crawl space.
Checks TS22–TS24 and TS40
hreflang requires indexable alternates, reciprocity and one controlled source.
Each locale URL should identify itself and its valid alternates with supported language or language-region codes. Alternates must be reciprocal and resolve to indexable candidate canonicals. Do not mix incomplete HTML, HTTP and sitemap declarations without a reconciliation process.
Automatic redirects based solely on IP or Accept-Language can prevent crawlers and users from reaching every locale. Provide stable URLs and an explicit language switch.
Checks TS25–TS27
Compare source HTML, rendered DOM and URL Inspection instead of debating JavaScript in the abstract.
Critical content, links, title, canonical and structured data should be compared across the server response and rendered output. Record failed resources and console errors. A client-rendered page can be indexable; a server-rendered page can still hide its substance behind interaction. The evidence is in the output, not the framework label.
If the public render differs from URL Inspection, the public audit reports the difference but does not invent Google’s state. Search Console evidence remains a separate field.
Checks TS28–TS30
Semantic HTML is a shared interface for browsers, assistive technology, search engines and agents.
One descriptive title and H1, a coherent heading hierarchy, landmarks, native links and useful alternative text make the document easier to interpret across consumers. This does not guarantee ranking. It removes ambiguity and reduces dependence on consumer-specific heuristics.
Validate the rendered document, not only the source. Duplicate IDs, interactive elements nested incorrectly and links without destinations often appear after components are composed.
Checks TS31–TS33
Structured data must describe visible entities without inventing evidence.
Parse every JSON-LD block, merge the graph by @id and compare important properties against visible content. Syntax validity is only the first gate. A technically valid rating that is not visible, a duplicated organisation with conflicting names, or a FAQ that does not exist in the page creates a semantic defect.
Google’s rich-result rules are product eligibility rules, not a complete Schema.org validator and not a ranking guarantee. Keep the broader entity graph coherent even when no rich result is available.
Checks TS34–TS36
Laboratory performance and field Core Web Vitals answer different questions.
| Signal | Context | Use | Limit |
|---|---|---|---|
| Lighthouse | Synthetic run under controlled conditions. | Debug opportunities and regressions. | Does not represent every real visit. |
| CrUX / CWV | Aggregated field data at the 75th percentile. | Assess real-user experience when data exists. | May be unavailable or aggregated at origin level. |
| RUM | Site-owned measurement. | Segment templates, devices and journeys. | Depends on implementation, consent and sampling. |
Use the current “good” thresholds as reference: LCP at or below 2.5 s, INP at or below 200 ms and CLS at or below 0.1, assessed at the 75th percentile. Record the date and source because thresholds and product treatment can evolve.
Checks TS37–TS40
HTTPS, URL normalisation, CDN behaviour and sitemap hreflang belong in the audit.
Verify the certificate chain, expiry, supported hostnames, mixed content and HSTS policy. Replay HTTP/HTTPS, www/non-www, case and slash variants. At the edge, compare cache status, redirects, Vary, locale behaviour and robot-specific responses. A correct origin response does not prove that the CDN serves the same result.
These checks are deliberately grouped because migrations often change several layers at once. Evidence must say where the response was observed and which headers were retained.
Check TS41
Critical technical SEO checks should be replayed in CI and after deployment.
Turn invariant rules into automated gates: status, redirect budget, indexability, canonical presence, robots accessibility, structured-data syntax, hreflang reciprocity and critical server-rendered content. Store fixture URLs by template and preserve the report as a build artefact.
Automation does not own the release decision. It detects defined regressions. A human still arbitrates context, severity and exceptions, with an owner and expiry date.
Checks TS42–TS44
Search crawlers, user-triggered agents and training crawlers need separate policies and tests.
Do not infer purpose from a generic “AI bot” label. OpenAI documents different tokens for search, user-triggered visits and training; Anthropic also documents distinct crawlers. Google-Extended is a separate product token and does not replace Googlebot. Record the operator’s documentation URL, policy owner and review date.
| Documented purpose | OpenAI | Anthropic | Decision to record |
|---|---|---|---|
| Search | OAI-SearchBot | Claude-SearchBot | Access, operator evidence, owner and review date. |
| User action | ChatGPT-User | Claude-User | Authorised journeys, authentication and expected traces. |
| Training | GPTBot | ClaudeBot | Rights policy kept separate from search visibility. |
curl -L -sS -o /dev/null \
  -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; OAI-SearchBot/1.0; +https://openai.com/searchbot)' \
  -w 'HTTP %{http_code} · redirects %{num_redirects} · final %{url_effective}\n' \
  https://www.example.com/page
For policy design and legal limits, use the dedicated protocol: Should you block AI crawlers and agents? HTTP access alone proves no actual presence in ChatGPT, Gemini, Claude or Perplexity.
Context before optimisation
Crawl budget is a priority for specific large sites or documented symptoms.
Google’s guidance primarily targets very large sites—around one million pages or more with weekly changes—medium or larger sites of roughly ten thousand pages with daily changes, or sites where a significant share remains “Discovered – currently not indexed”. These are reference orders of magnitude, not universal boundaries.
On a fifty-page B2B site, crawl budget often distracts from more plausible causes: orphan pages, contradictory canonicals, weakly differentiated content, broken rendering or missing internal links.
Public example · Edikka
What a public audit of this URL establishes—and what it must refuse to claim.
Observation performed on 22 August 2026 from an unauthenticated external connection. This example demonstrates evidence discipline; it is not presented as a complete audit of the entire domain.
| Observation | Public state | Evidence | Allowed conclusion |
|---|---|---|---|
| Final response | HTTP 200. | GET request with redirects followed. | The page responds publicly from this test point. |
| Canonical | Absolute and self-referencing. | Source HTML. | The page declares this URL; Google may select another. |
| Robots | index, follow; path not blocked by public robots.txt. | Source HTML and robots.txt. | No public block observed in these two layers. |
| Sitemap | URL present. | Public sitemap.xml. | The URL is declared; indexation is not proven. |
| Server content | H1 and editorial content in HTML response. | Source received without running JavaScript. | The main content does not wholly depend on client rendering. |
| JSON-LD | WebPage, Article and FAQ exposed. | application/ld+json scripts. | The graph exists; use by a consumer is not guaranteed. |
Current indexation, Google-selected canonical, real Googlebot requests, field Core Web Vitals, impressions, rankings and the causal effect of this update require Search Console, logs or a measurement period. They are not inferred from HTML.
Download the JSON evidence artefact: commands, timestamps, selected headers, SHA-256 fingerprints, allowed conclusions and limitations.
Decision without a false score
Status, severity and decision are separate fields.
| Field | Values | Question answered |
|---|---|---|
| Status | Not tested · Compliant · Non-compliant · Not applicable. | What was observed? |
| Severity | Blocking · Major · Minor · Information. | What risk does failure create? |
| Decision | NO-GO · Arbitration required · GO with reservations. | May this release proceed in context? |
The workbook does not compute a score out of 100. An average would dilute a critical defect: 43 successful checks do not compensate for an accidental noindex on the offer page. One failed Blocking check—or an applicable Blocking check left untested—imposes NO-GO; a failed Major check requires documented arbitration.
Execution and non-regression
Staging, D+1, D+7 and D+30 answer different questions.
| When | Priority checks | Decision | Evidence |
|---|---|---|---|
| Before launch | HTTP, directives, canonical, links, sitemap, hreflang, render, structured data. | Signed GO / NO-GO. | Dated workbook, exports and screenshots. |
| D+1 | Codes, chains, robots, noindex, canonical, sitemap, forms and analytics. | Fix blockers immediately. | Production crawl versus baseline. |
| D+7 | Logs, Pages report, sitemaps, server errors, key canonicals. | Prioritise abnormal families. | Template-level segments. |
| D+30 | Indexation, Search performance, field CWV when available, persistent defects. | Close, extend or open causal analysis. | Comparable window and change log. |
For a redesign, combine this protocol with the URL-by-URL SEO migration protocol and pre-launch website acceptance testing. The Edikka website redesign offer describes the commercial scope that brings these disciplines together.
Shortcuts to remove
Eight attractive statements become false when their context is removed.
| Shortcut | Verifiable wording |
|---|---|
| “Disallow deindexes.” | Disallow limits crawling for compliant robots; the URL may remain known. |
| “noindex in robots.txt works.” | Google does not support it there; use accessible meta robots or X-Robots-Tag. |
| “Canonical imposes the URL.” | rel=canonical is a strong signal; the engine keeps the final choice. |
| “A sitemap guarantees indexation.” | It declares canonical candidates; it does not guarantee indexation. |
| “JavaScript prevents SEO.” | Risk comes from absent, blocked or incorrectly rendered content and links. |
| “Schema.org improves rankings.” | Structured data can support understanding and features; no position gain is guaranteed. |
| “Lighthouse 100 proves speed.” | Lighthouse is a lab test; field CWV is assessed separately. |
| “Every site has a crawl-budget problem.” | It becomes a priority at scale or with documented symptoms. |
Open resources
Download, replay and cite the method.
This article and the Edikka Technical SEO Audit Grid v1.1 are published under CC BY 4.0. Reuse is allowed with attribution to Edikka and this canonical URL. Files are available without a form.
v1.1 · 22 August 2026. The protocol expands to 44 checks across 13 domains, publishes the complete inventory in HTML, adds HTTPS/HSTS, normalisation, CDN, sitemap hreflang, CI and AI-crawler checks, and attaches JSON evidence to the self-audit. It claims no market statistic without a preregistered panel.
Primary sources
Documents consulted on 22 August 2026.
- RFC 9309 · Robots Exclusion Protocol.
- RFC 9110 · HTTP Semantics.
- Google Search Central · Introduction to robots.txt.
- Google Search Central · Robots meta and X-Robots-Tag.
- Google Search Central · Canonicalisation.
- Google Search Central · Build and submit a sitemap and Sitemaps.org.
- Google Search Central · Crawlable links.
- Google Search Central · Localised versions and hreflang.
- Google Search Central · Locale-adaptive pages.
- Google Search Central · JavaScript SEO basics.
- Google Search Central · Structured-data policies.
- web.dev · Core Web Vitals thresholds.
- Google · Crawl budget for large sites.
- RFC 6797 · HTTP Strict Transport Security.
- OpenAI · Crawlers and purposes.
- Google · Google-Extended.
- Anthropic · Claude crawlers.
A technical foundation is solid only when its decision can be replayed.
The goal is not a more impressive audit. It is knowing exactly what was tested, what remains unknown and what must stop a release.
Keep layers separate
HTTP, robots, rendering, indexation, Google's canonical and field data do not prove one another. Every item of evidence keeps its scope.
Name the unknown
Not tested, not applicable and non-compliant are different states. Merging them creates confidence instead of a decision.
Reject the reassuring average
An accidental noindex is not offset by 43 successful checks. Severity and risk ownership take precedence over a score.
Go further on this topic
Additional answers to clarify the key points covered in this article.